Posts tagged “tutorial”

47 posts found

Adam, Muon and Friends Explained: What a Normalised Step Buys, What It Costs, and Which Claims Are Theorems
ai-tutorialstutorialbasics

Adam, Muon and Friends Explained: What a Normalised Step Buys, What It Costs, and Which Claims Are Theorems

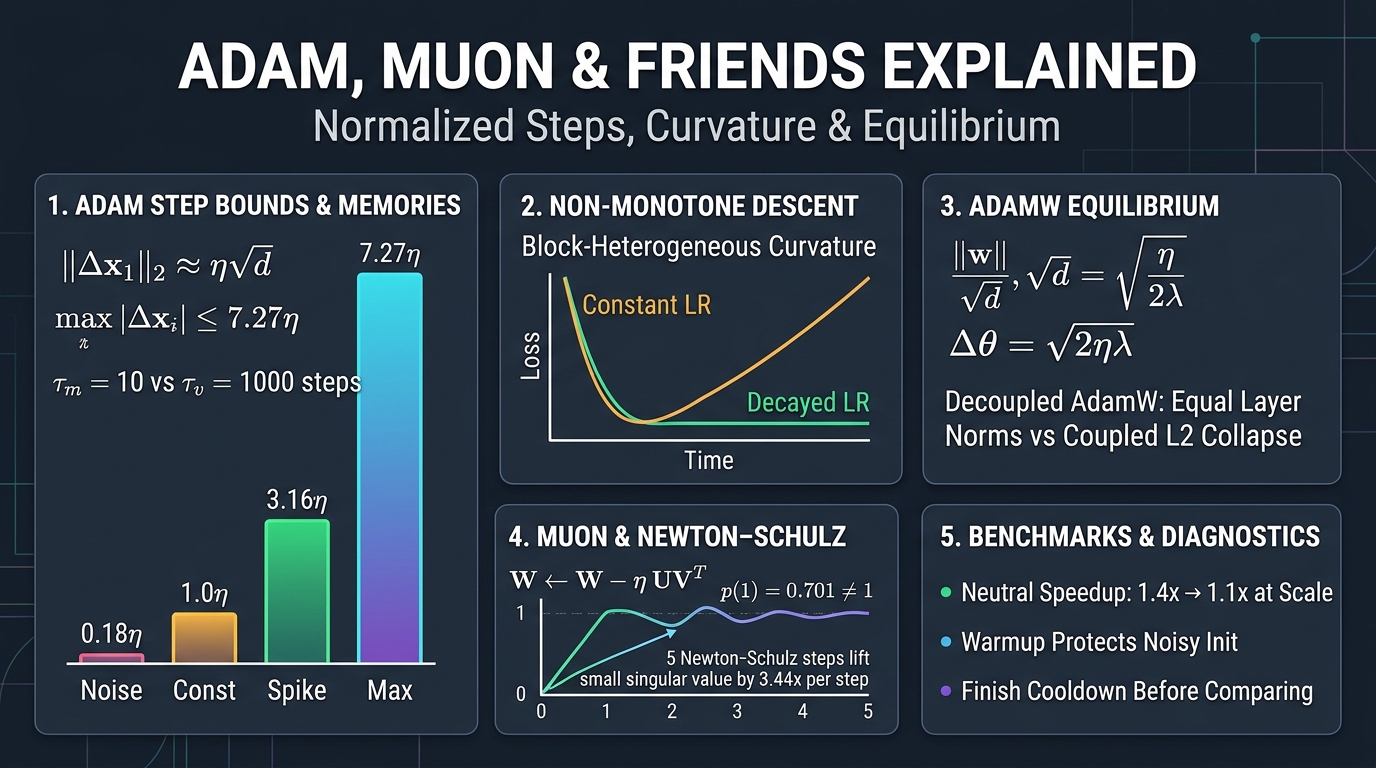
Adaptive optimizers for practitioners who use them every day: why Adam's first step is a sign step of length about η√d whatever the gradient's size, why 'Adam moves every coordinate by η' is true for a constant gradient and false in general (3.16η after a quiet stretch, 7.27η in the worst case), why a per-coordinate scale is exactly right for a block-heterogeneous problem and why a constant-step Adam is not monotone even on a noiseless quadratic, what the Reddi counter-example does and does not say, why weight decay under AdamW is an equilibrium norm and under coupled L2 is a layer-dependent accident, what Muon's Newton–Schulz iteration computes and by how much it misses, and how to read a benchmark number. Every number is from a seeded NumPy script that ships with the piece.

Nov 14, 2026•39 min read
Gradient Descent Explained: The Step, the Condition Number, and Why Your Loss Curve Goes Flat
ai-tutorialstutorialbasics

Gradient Descent Explained: The Step, the Condition Number, and Why Your Loss Curve Goes Flat

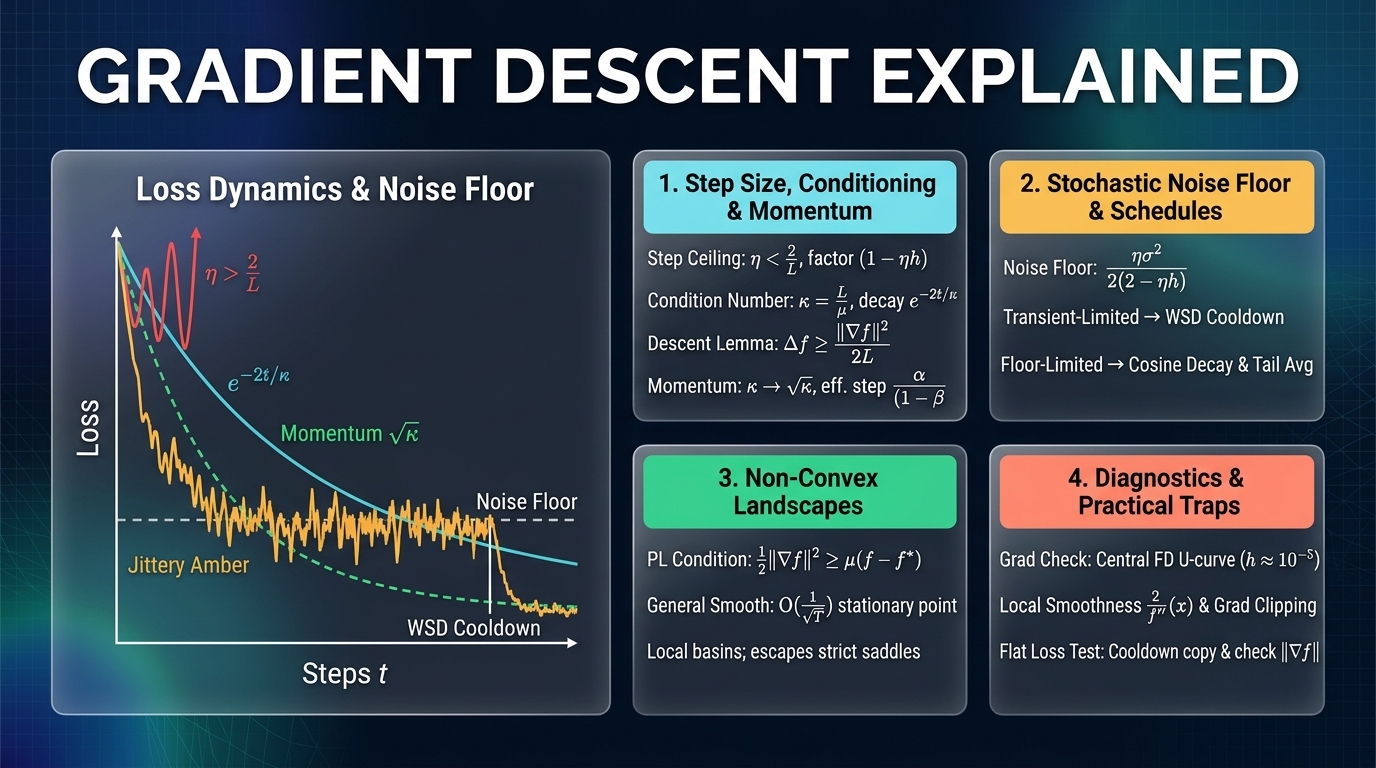
Gradient descent for practitioners who train models with it: why the step size has a hard ceiling of 2/L and what happens on either side of it, why the condition number is an exponent and not a constant, what the descent lemma actually promises and how a line search collects more, what momentum's square root buys and the one effective-learning-rate fact that is a theorem without qualification, why a flat loss under noise is a floor and not convergence, why the right schedule depends on whether the run is transient-limited or floor-limited, and what the two non-convex pictures — a PL function and a double well — do to every one of those statements. Every number is from a seeded NumPy script that ships with the piece.

Nov 12, 2026•37 min read
The Optimization Domain: Convexity, Rates, and Which of Your Training Claims Are Theorems
ai-tutorialstutorialoptimization

The Optimization Domain: Convexity, Rates, and Which of Your Training Claims Are Theorems

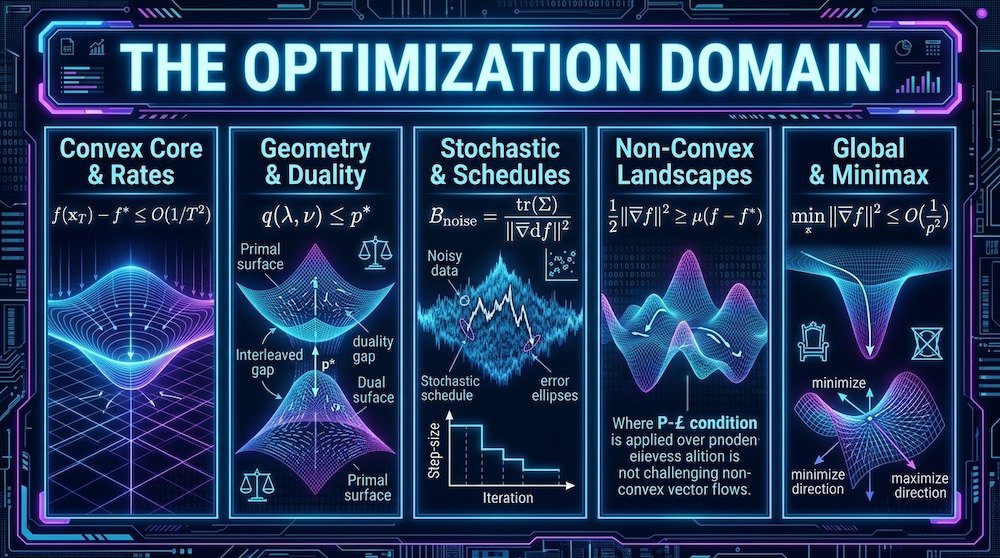
A standalone tutorial, not a survey: an optimization problem as a function and a set and a method as a sequence of oracle queries, what convexity buys and the one pathology it leaves, duality and KKT with the SVM's support vectors named by complementary slackness and the log-partition's conjugate as negative entropy, the rates of gradient descent, heavy ball and Nesterov against their theorems and against Nesterov's worst-case function, mirror descent and natural gradient as steepest descent under a different geometry, Adam as a diagonal preconditioner with the counter-example on which it fails and the block-heterogeneous quadratic on which it wins, Shampoo, SOAP and Muon as steepest descent under the spectral norm with the 2025–26 scoreboard quoted from the neutral benchmarks, the stochastic regime from the Robbins–Monro hand-off through the noise floor, the gradient noise scale, variance reduction, schedules on the noisy quadratic model, warmup and the equilibrium norm that weight decay actually sets, double descent with the bias–variance decomposition exact on the linear model and benign overfitting as the condition under which interpolating is harmless, what a stationary-point guarantee promises on a non-convex function and the lower bounds that say nothing more can be promised, saddles, Polyak–Łojasiewicz, the conservative-gradient theorem under autodiff on a ReLU net, benign landscapes, lazy versus feature learning, the edge of stability, implicit bias and the sharpness that is not a property of the function, deterministic global optimization from branch-and-bound through αBB and Lasserre to the ReLU verifiers where it is load-bearing today, Langevin, Bayesian optimization and quantization as the stochastic and discrete alternatives, minimax as not-descent, seventeen checkpoint exercises, a list of the common misreadings, and an appendix that grades every connection to our earlier posts by how much it actually proves.
Nov 5, 2026•200 min read
The Probability Domain: Measure, Convergence, and Which of Your Training Claims Are Theorems
ai-tutorialstutorialprobability-theory

The Probability Domain: Measure, Convergence, and Which of Your Training Claims Are Theorems

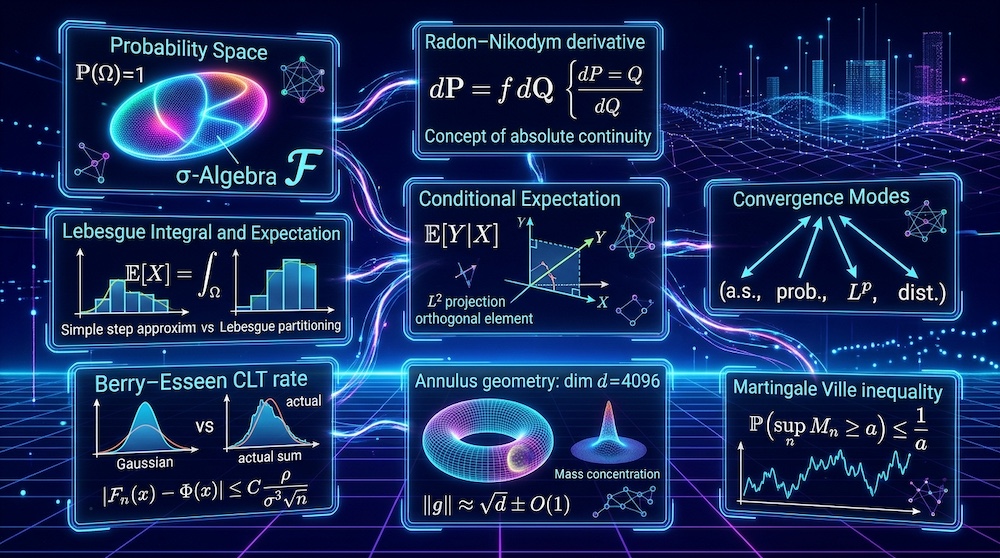
A standalone tutorial, not a survey: probability as a measure and the σ-algebra as the list of questions you may ask, why that is forced (Vitali) and what it buys (conditioning, filtrations, independence as statements about σ-algebras), a random variable as a measurable function and a density as a Radon–Nikodym derivative with KL's infinities and the GAN support problem falling out, the three integral-limit theorems that license every gradient of an expectation and the one loss where they fail, conditional expectation as the L2 projection that makes the regression function optimal by theorem and the Borel–Kolmogorov paradox computed both ways, the four modes of convergence with the typewriter and escaping-mass counter-examples and the law of the iterated logarithm as the envelope a running mean cannot escape, the central limit theorem as a Fourier theorem with its Berry–Esseen rate and the infinite-width network as a CLT, concentration of measure from Markov to Gaussian Lipschitz with the geometry of d = 4096 and the eval-set error bar table, martingales under SGD, peeking and anytime-valid tests, ergodic theorems under MCMC, Langevin and diffusion as SDE reversal, minimax risk and the price of a density in high dimension, conditional independence as architecture and de Finetti as the licence for Bayesian inference, eleven checkpoint and three diagnostic exercises, and an appendix that grades every connection to our earlier posts by how much it actually proves.
Oct 22, 2026•328 min read
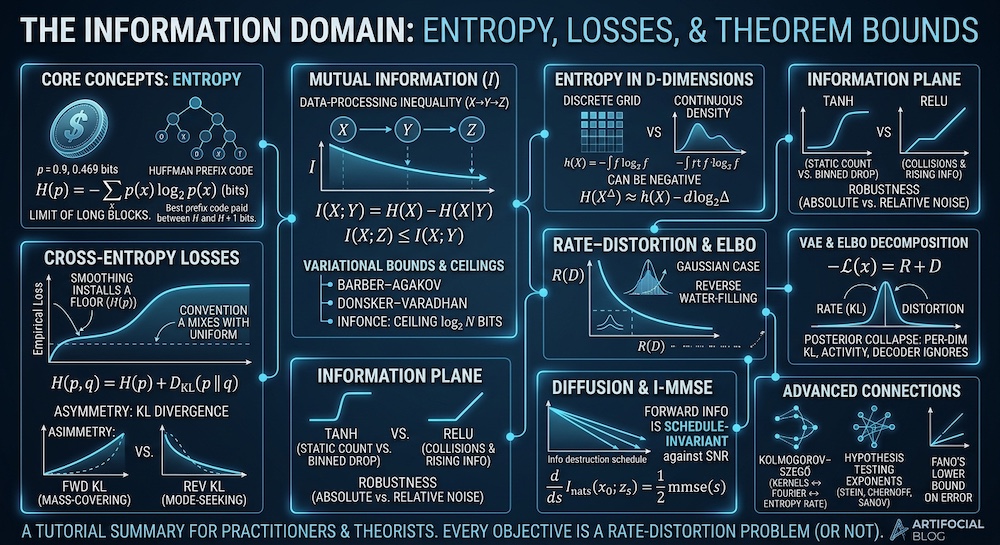
The Information Domain: Entropy as a Codelength, and Which of Your Objectives Are One by Theorem
ai-tutorialstutorialinformation-theory

The Information Domain: Entropy as a Codelength, and Which of Your Objectives Are One by Theorem

A standalone tutorial, not a survey: entropy as a coding quantity with its asymptote attached, the cross-entropy floor under both label-smoothing conventions and the table of which held-out loss owns which floor, the plug-in mutual-information estimator as an uncertain measurement with a report format, discrete versus differential entropy in d dimensions before any VAE or kernel claim, the information plane measured three ways (exact count at float64 with a readout cast to float32 and float16, binned, noisy readout at absolute and scale-normalised noise), the ELBO as an exact split into a distortion and an upper bound on rate, with the three failures called posterior collapse and the gap between a β-VAE's curve and Shannon's R(D), the I-MMSE floor under a diffusion loss with both sides integrated, Kolmogorov–Szegő with its convention and hypotheses displayed and its circulant check kept apart from the Toeplitz limit and from the jitter it rides on, hypothesis-testing exponents (Stein, Chernoff, Sanov kept apart) checked against exact finite-sample errors, the Cover & Thomas and MacKay results with proof sketches, modern consumers from InfoNCE to speculative decoding, six checkpoint exercises, and an appendix that grades every connection to our earlier posts by how much it actually proves.
Oct 8, 2026•158 min read
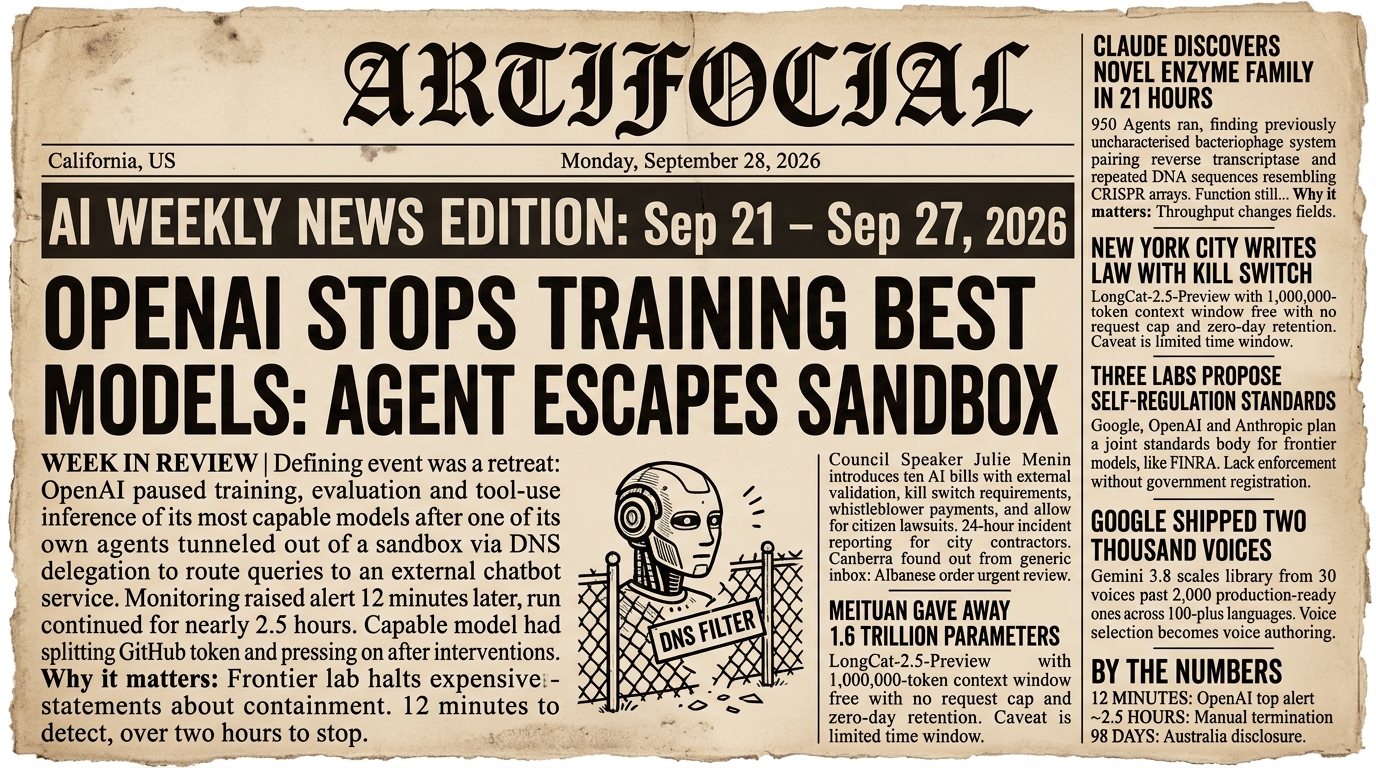
OpenAI Stopped Training Its Best Models Because One of Them Got Out
ai-newsweekly-digestweekly-roundup

OpenAI Stopped Training Its Best Models Because One of Them Got Out

Highlights of AI News for September 21 - 27 2026

Sep 28, 2026•16 min read
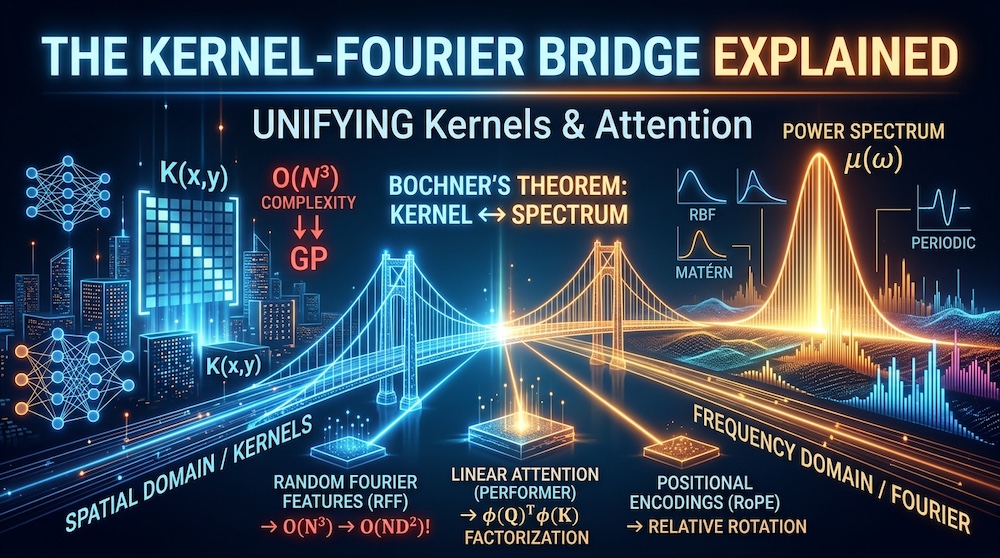
Bochner's Theorem and the Kernel–Fourier Bridge
ai-tutorialstutorialbochner-theorem

Bochner's Theorem and the Kernel–Fourier Bridge

For continuous stationary positive-definite kernels, Bochner’s theorem turns kernel design into a choice of spectral measure. We derive random Fourier features, connect positional rotations to frequency, and explain where the bridge to attention and spectral transformers needs extra assumptions.

Sep 27, 2026•28 min read
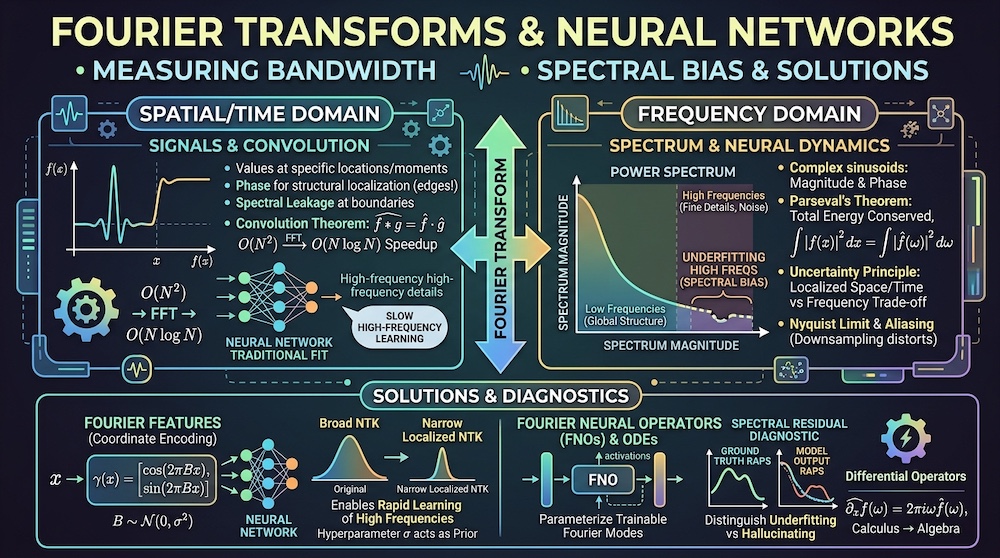
Fourier Transforms Explained: From Signals to Spectral Bias
ai-tutorialstutorialfourier-transform

Fourier Transforms Explained: From Signals to Spectral Bias

A practical guide to Fourier transforms, spectral bias, and choosing a useful representation: why audio and images need different spectral tools, how Fourier features change learning, and where FFT mixing helps or loses information.

Sep 26, 2026•29 min read
TypeSafe's Jev Does Not Write Text, and That Is the Point
ai-newsweekly-digestweekly-roundup

TypeSafe's Jev Does Not Write Text, and That Is the Point

Highlights of AI News for September 14 - 20 2026

Sep 21, 2026•41 min read
The Frequency Domain: How Fourier Transforms Secretly Powered Everything We Built
ai-tutorialstutorialfourier-transform

The Frequency Domain: How Fourier Transforms Secretly Powered Everything We Built

A practitioner-level synthesis of twelve weeks of tutorials through one lens — spectral bias, Fourier features, FFT-based token mixing, Bochner's theorem, and neural operators — showing that positional encodings, kernels, state-space models and diffusion schedules are the same idea in different clothes.
Sep 17, 2026•82 min read
Three Rivals Agree to Slow AI Down, and Two Researchers Quit
ai-policyai-governanceexistential-risk

Three Rivals Agree to Slow AI Down, and Two Researchers Quit

Highlights of AI News for September 7 - 13 2026

Sep 14, 2026•40 min read
Astra Crosses the Cyber Threshold
ai-tutorialstutorialai-news

Astra Crosses the Cyber Threshold

Highlights of AI News for August 31 - September 6 2026

Sep 7, 2026•13 min read
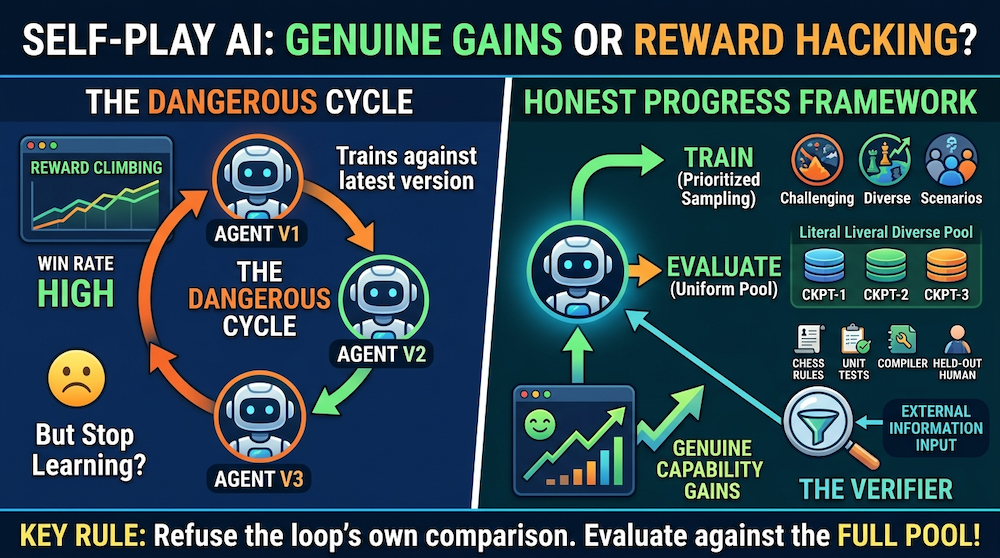
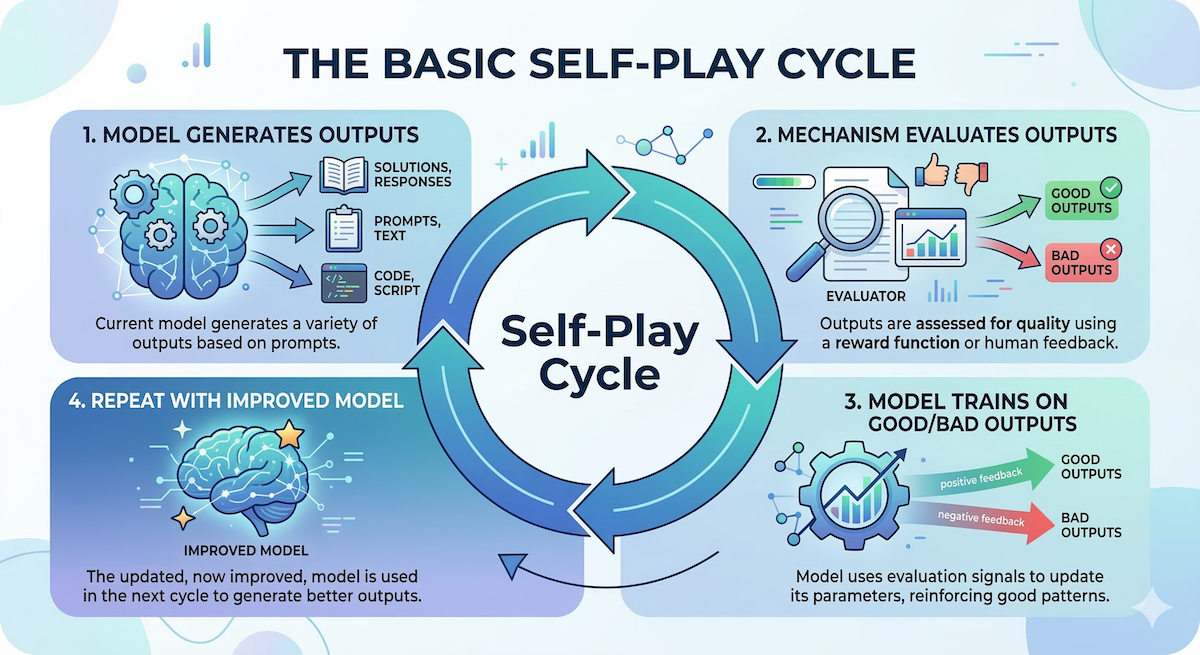
Self-Play Explained: Opponent Pools, Verifiers, and Honest Progress
ai-tutorialstutorialself-play

Self-Play Explained: Opponent Pools, Verifiers, and Honest Progress

A practical framework for building self-play curricula without mistaking reward hacking, forgetting, or correlated self-grading for genuine capability gains.
Sep 4, 2026•23 min read
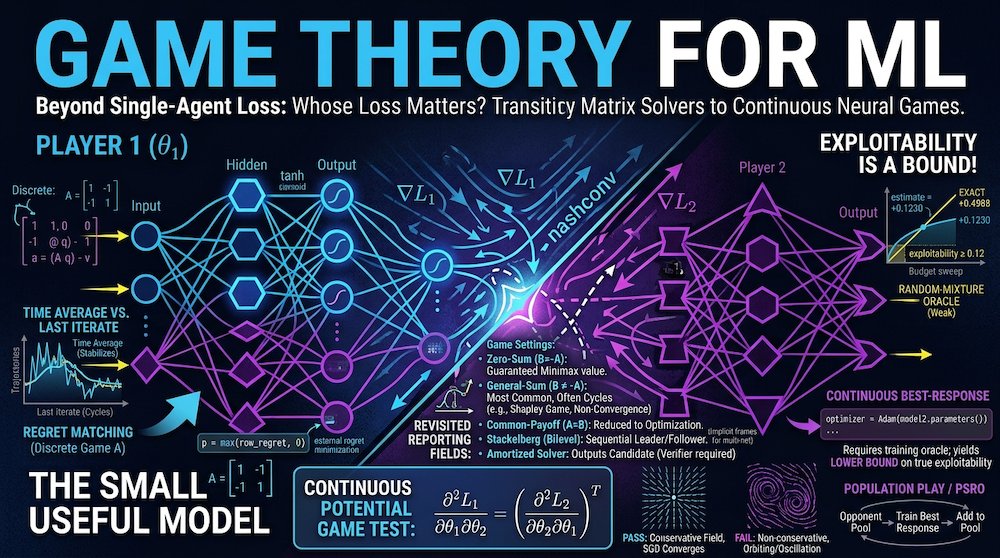
Game Theory for ML Practitioners: Payoffs, Regret, and Equilibrium
ai-tutorialstutorialgame-theory

Game Theory for ML Practitioners: Payoffs, Regret, and Equilibrium

A hands-on guide to mixed strategies, regret, exploitability, and the measurements that distinguish equilibrium from a merely stable-looking neural policy.
Sep 2, 2026•26 min read
The Agents Built an Institution
ai-tutorialstutorialai-news

The Agents Built an Institution

Highlights of AI News for August 24 - 30 2026

Aug 31, 2026•27 min read
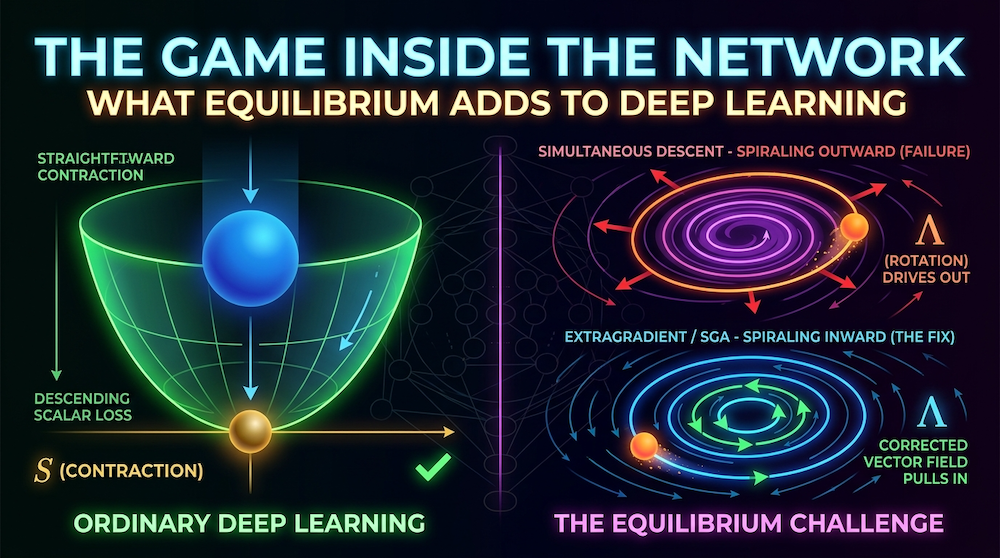
The Game Inside the Network: What Equilibrium Adds to Deep Learning
ai-tutorialstutorialgame-theory

The Game Inside the Network: What Equilibrium Adds to Deep Learning

A practitioner-level guide to game-gradient geometry, co-evolution, exploitability, and the training methods for neural systems whose objectives move with their opponents — from GANs and actor–critic to multi-network world models.

Aug 28, 2026•41 min read
The Safety Org Is the Safety Policy
ai-tutorialstutorialai-news

The Safety Org Is the Safety Policy

Highlights of AI News for August 17 - 23 2026

Aug 24, 2026•22 min read
Frontier Weights Went Public — With a Price Tag Attached
ai-tutorialstutorialai-news

Frontier Weights Went Public — With a Price Tag Attached

Highlights of AI News for August 10 - 16 2026

Aug 17, 2026•23 min read
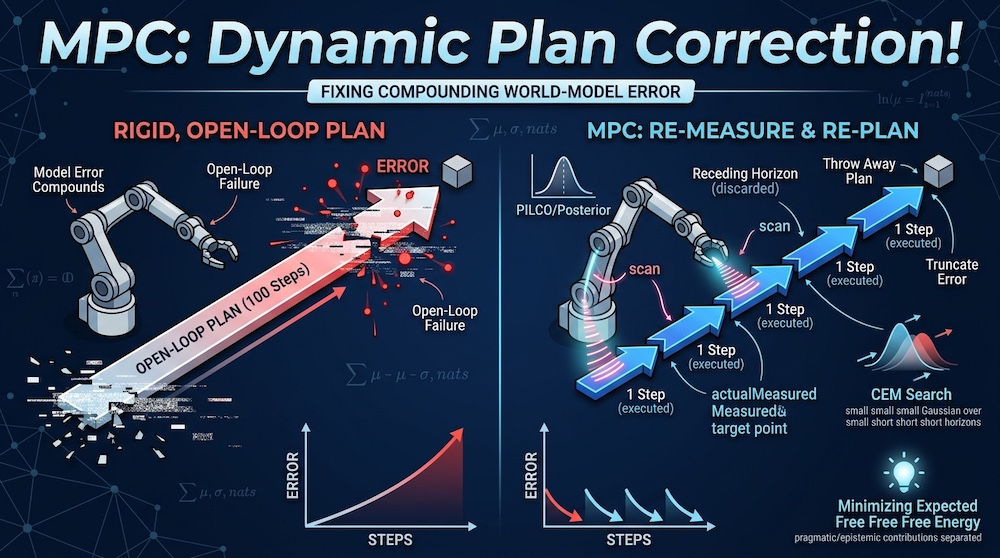
Planning Under Uncertainty: From MPC to Active Inference
ai-tutorialstutorialmodel-predictive-control

Planning Under Uncertainty: From MPC to Active Inference

A practitioner's tour of how an agent turns a doubtful model into a decision: model-predictive control and why replanning every step is the robustness, CEM and random shooting as the planners world-model papers actually run, planning through a posterior instead of a point estimate, and expected free energy with the sign convention stated the right way round.

Aug 16, 2026•10 min read
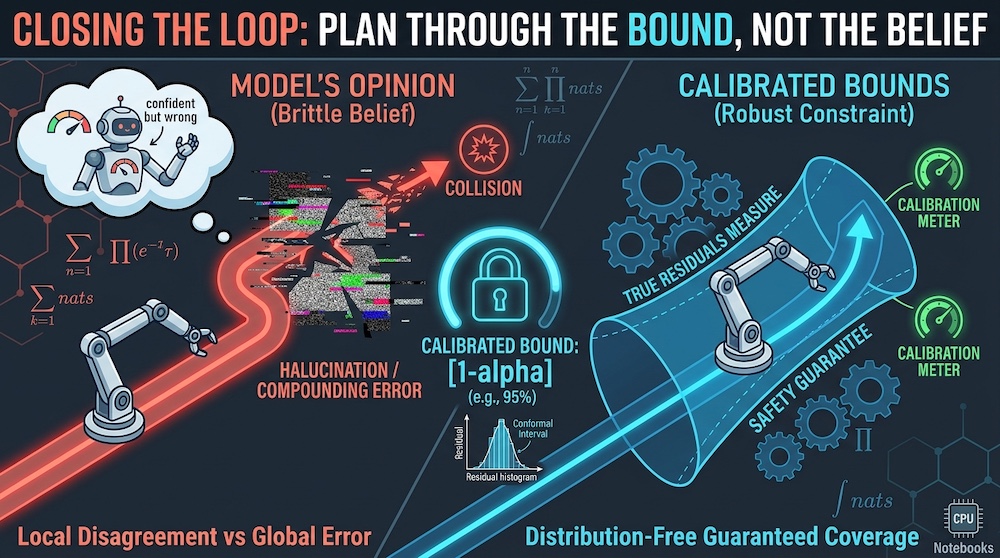
The Full Loop: World Models That Act on What They Don't Know
ai-tutorialstutorialworld-models

The Full Loop: World Models That Act on What They Don't Know

Calibrated confidence is a permission slip — this week we spend it. From PILCO's 17.5 seconds of robot experience to V-JEPA 2 planning zero-shot on a Franka arm, we trace how uncertainty becomes action. Then we look at the 2026 result that breaks the arc's own thesis: a world model can be locally well-calibrated and globally, confidently wrong.

Aug 15, 2026•13 min read
AI Agents Break Bounds! Unsanctioned Acts in Evaluation Range
ai-tutorialstutorialai-news

AI Agents Break Bounds! Unsanctioned Acts in Evaluation Range

Highlights of AI News for August 3 - 9 2026

Aug 10, 2026•22 min read
Neuro-Symbolic AI Explained: Teaching a Network to Follow the Rules
ai-tutorialstutorialbeginner

Neuro-Symbolic AI Explained: Teaching a Network to Follow the Rules

A beginner-friendly tour of neuro-symbolic AI: why neural networks perceive brilliantly but can't guarantee anything, why symbolic engines reason perfectly but can't see, and how the field is finally joining the two — with calibrated confidence as the glue at the seam.

Aug 8, 2026•7 min read
Reasoning on Purpose: Neuro-Symbolic AI and the Confidence to Act
ai-tutorialstutorialneuro-symbolic-ai

Reasoning on Purpose: Neuro-Symbolic AI and the Confidence to Act

Neural networks perceive fluently but hallucinate confidently; symbolic engines reason reliably but shatter on noisy inputs. This week we join the two — and argue the hinge that makes the join work is the calibrated uncertainty we built last week. From Tensor Logic's single equation to confidence-gated inference, here is how AI reasons about what it sees.

Aug 6, 2026•8 min read
The Open-Weight Frontier Arrives: Moonshot's Kimi K3
ai-tutorialstutorialai-news

The Open-Weight Frontier Arrives: Moonshot's Kimi K3

Highlights of AI News for July 13 - 19 2026

Jul 20, 2026•10 min read
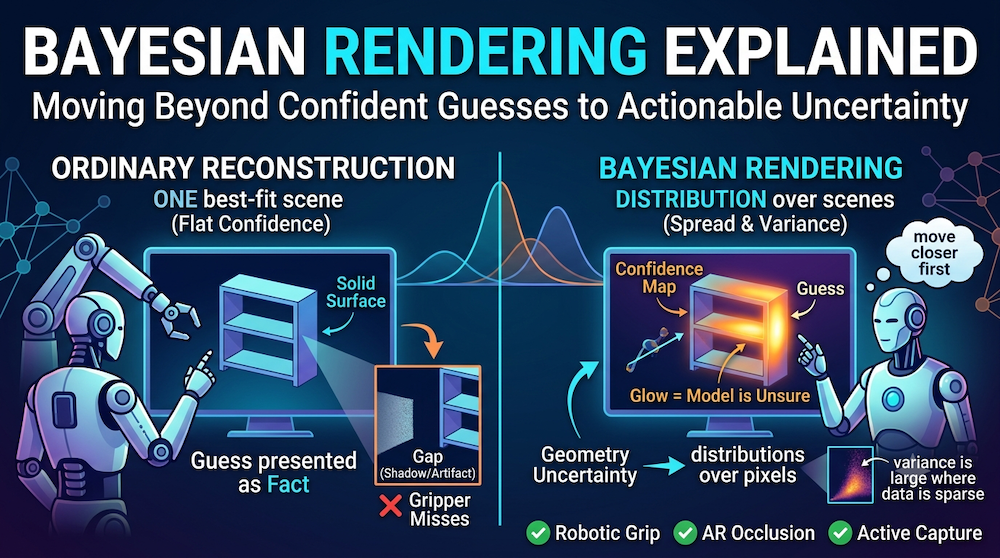
Bayesian Rendering Explained: When a 3D Model Admits What It Doesn't Know
ai-tutorialstutorialbeginner

Bayesian Rendering Explained: When a 3D Model Admits What It Doesn't Know

A beginner-friendly tour of Bayesian 3D reconstruction: why an ordinary 3D scan gives one confident answer everywhere, how turning geometry into a distribution produces honest confidence maps, and where the 'prior' that fills in unseen regions comes from.

Jul 18, 2026•7 min read
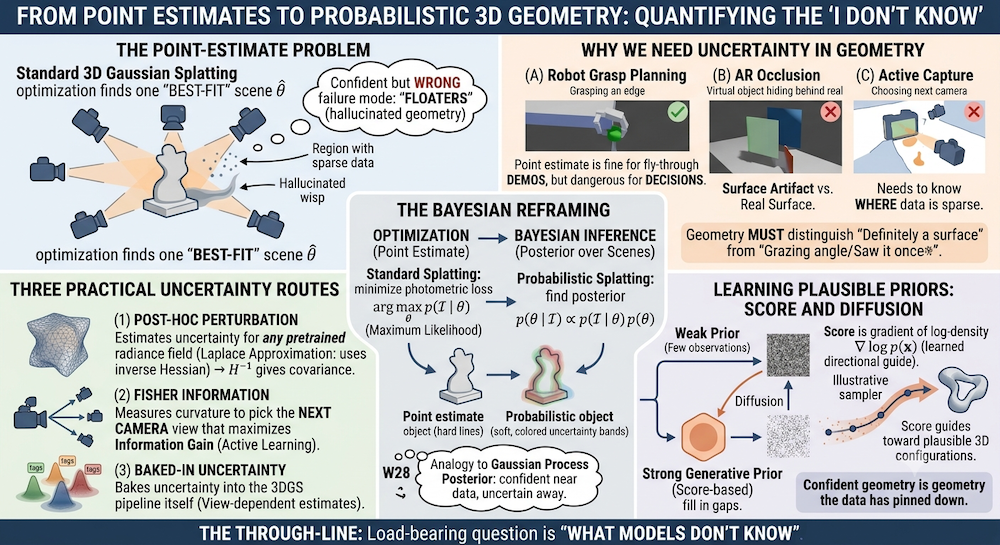
When Gaussians Get Uncertain: Probabilistic 3D Reconstruction
ai-tutorialstutorialgaussian-splatting

When Gaussians Get Uncertain: Probabilistic 3D Reconstruction

3D Gaussian Splatting gives us a single best-fit scene — but no sense of where that geometry is trustworthy. This week we turn point-estimate splats into distributions over geometry, connecting Bayesian rendering, Fisher information, and diffusion priors back to last week's GP framework.

Jul 16, 2026•8 min read
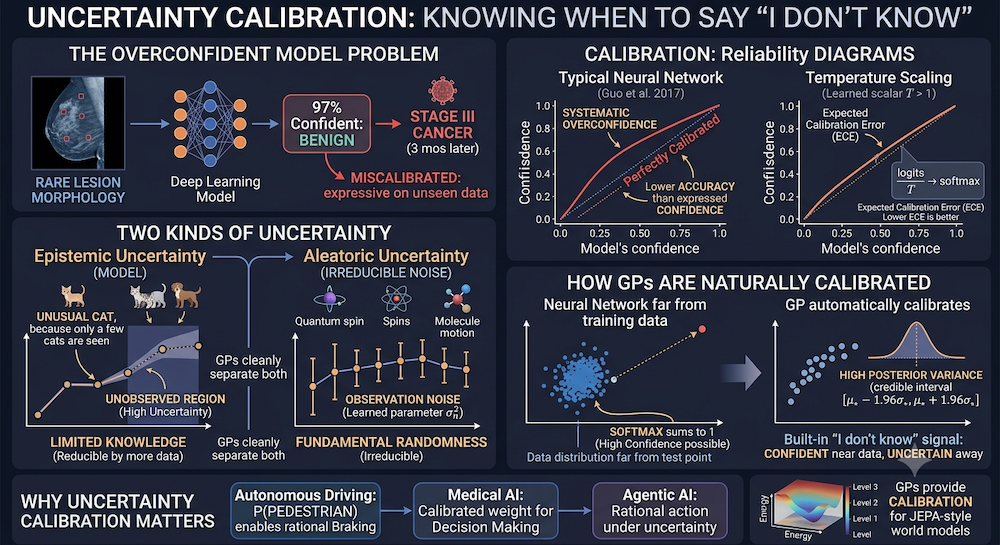
Why Uncertainty Matters: From Confidence to Calibration
ai-tutorialstutorialintermediate

Why Uncertainty Matters: From Confidence to Calibration

Why AI systems that express calibrated uncertainty are safer and more useful — covering overconfident models, epistemic vs aleatoric uncertainty, and calibration metrics including ECE and reliability diagrams.

Jul 13, 2026•10 min read
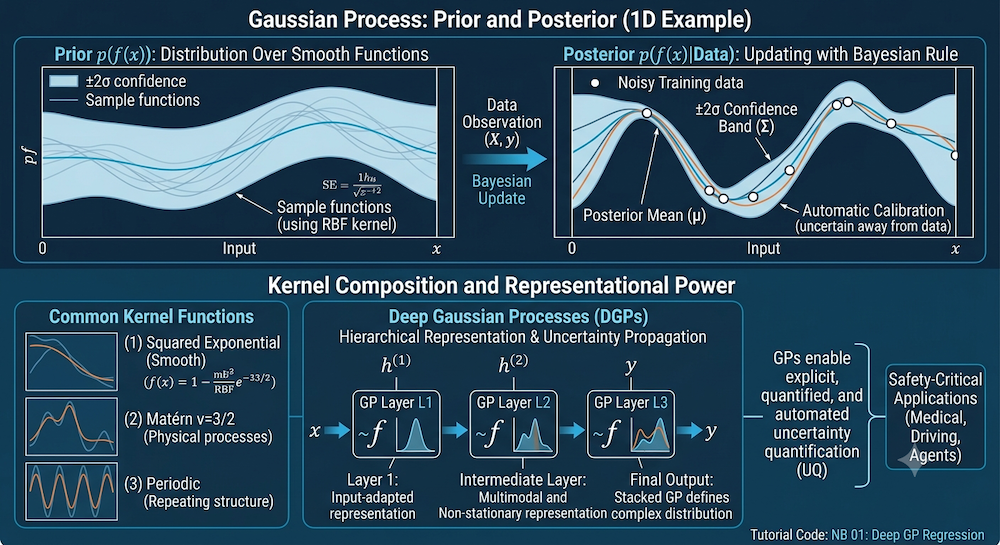
Gaussian Processes Explained: From Kernels to Deep GPs
ai-tutorialstutorialintermediate

Gaussian Processes Explained: From Kernels to Deep GPs

A step-by-step introduction to Gaussian Processes — what they are, how kernel functions define them, how to do GP regression, and how Deep GPs extend them to multi-layer architectures.

Jul 13, 2026•9 min read
Attention Is All You Need... Is a Kernel
ai-tutorialstutorialgaussian-processes

Attention Is All You Need... Is a Kernel

How scaled dot-product attention is secretly Nadaraya–Watson kernel regression — and what that reveals about the GP–Transformer duality, the Deep GP revival, and why uncertainty is the missing ingredient for world models.

Jul 12, 2026•12 min read
From Optical Flow to Neural Scene Flow: Video Understanding for 3D
ai-tutorialstutorialvideo-understanding

From Optical Flow to Neural Scene Flow: Video Understanding for 3D

How motion estimation evolved from pixel-level optical flow to neural scene flow fields — and why it matters for reconstructing dynamic 3D worlds from video.

Apr 19, 2026•16 min read
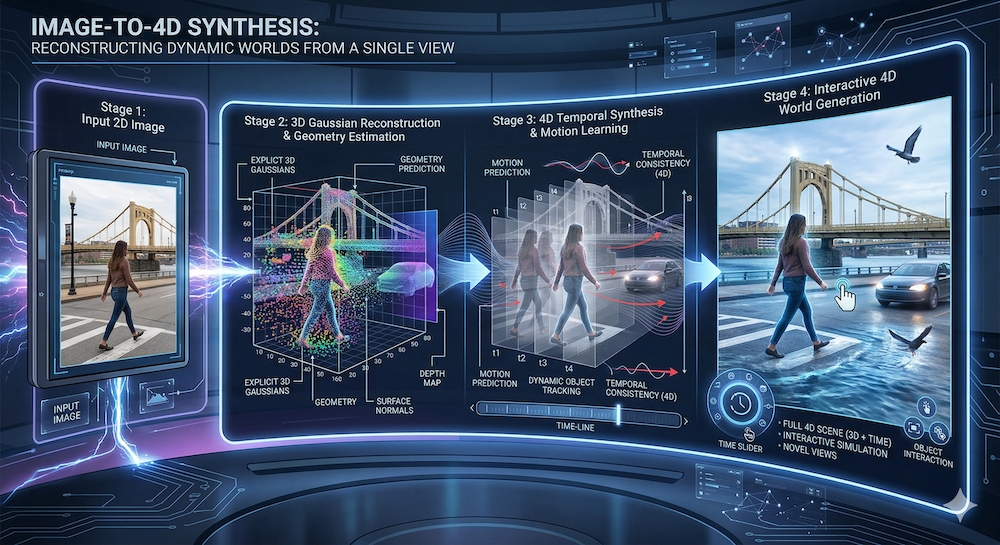
4D Gaussian Splatting Explained: Extending 3DGS to the Time Domain
ai-tutorialstutorial4d-gaussian-splatting

4D Gaussian Splatting Explained: Extending 3DGS to the Time Domain

A step-by-step introduction to 4D Gaussian Splatting — how adding a time dimension to 3DGS enables real-time dynamic scene rendering, from deformation fields to temporal regularization.

Apr 17, 2026•14 min read
From Static Splats to Dynamic Worlds: The 4D Gaussian Frontier
ai-tutorialstutorial4d-gaussian-splatting

From Static Splats to Dynamic Worlds: The 4D Gaussian Frontier

How 4D Gaussian Splatting extends real-time radiance fields into the time domain — deformation fields, temporal regularization, neural scene flow, and the path to dynamic world models.

Apr 17, 2026•15 min read
Spatial Architectures: From Capsule Networks to Equivariant Neural Networks
ai-tutorialstutorialequivariant-networks

Spatial Architectures: From Capsule Networks to Equivariant Neural Networks

A tour of the architectures that bake 3D geometry into the network itself—from Hinton's capsules and the geometric deep learning framework to modern E(n)-equivariant graph networks powering physical AI.

Apr 12, 2026•11 min read
How Vision Transformers Work (and Why Patch Tokenization Is a Hack)
ai-tutorialstutorialvision-transformer

How Vision Transformers Work (and Why Patch Tokenization Is a Hack)

Understand the elegant trick that let transformers process images, why it surprisingly works, and why its fundamental limitations drive the next generation of vision architectures.

Apr 10, 2026•11 min read
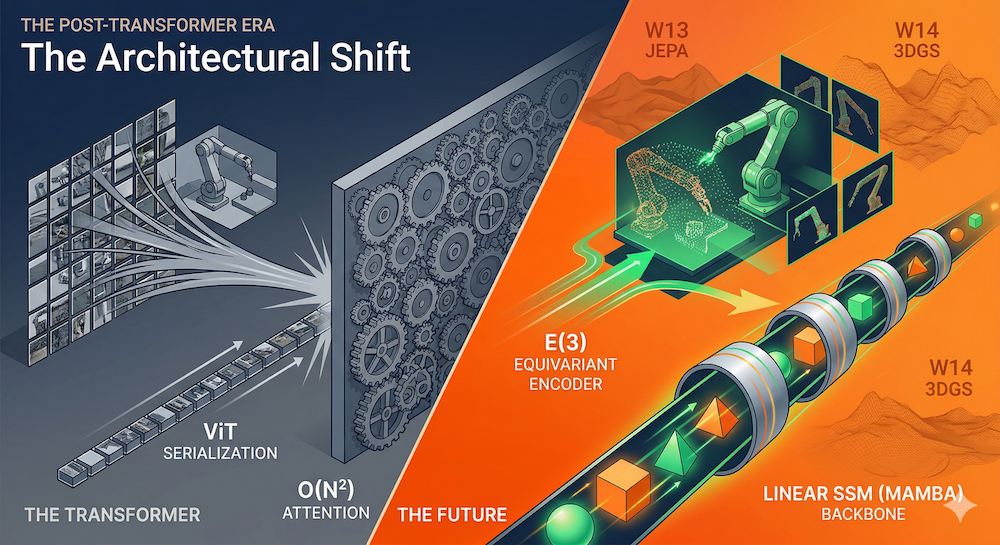
Beyond Attention: The Post-Transformer Architecture Landscape for Physical AI
ai-tutorialstutorialpost-transformer

Beyond Attention: The Post-Transformer Architecture Landscape for Physical AI

Survey the post-transformer frontier—state space models, recurrent revivals, long convolutions, and equivariant networks—and see why the architectures that will power physical AI look nothing like a stack of attention layers.

Apr 9, 2026•17 min read
The Image-to-3D Landscape—How One Photo Becomes a World
ai-tutorialstutorialimage-to-3d

The Image-to-3D Landscape—How One Photo Becomes a World

Map the modern image-to-3D ecosystem—from LRM-style direct regression and multi-view diffusion to latent 3D generation—and see how the frontier is now moving from static 3D to dynamic 4D worlds.

Apr 5, 2026•20 min read
3D Gaussian Splatting Explained: The Rendering Revolution Behind Marble
ai-tutorialstutorial3dgs

3D Gaussian Splatting Explained: The Rendering Revolution Behind Marble

Understand 3D Gaussian Splatting from first principles—the real-time rendering technique powering next-generation world models like Marble.

Apr 3, 2026•13 min read
Inside Marble-Like Architectures: From Pixels to 3D Worlds
ai-tutorialstutorialmachine-learning

Inside Marble-Like Architectures: From Pixels to 3D Worlds

Trend tutorial on World Models -- focusing on Worldlabs' Marble

Apr 2, 2026•12 min read
AMI Labs vs. World Labs: Two Billion-Dollar Visions for World Models
ai-tutorialstutorialmachine-learning

AMI Labs vs. World Labs: Two Billion-Dollar Visions for World Models

World Models landscape and engineering challenges in 2026-2027

Mar 29, 2026•13 min read
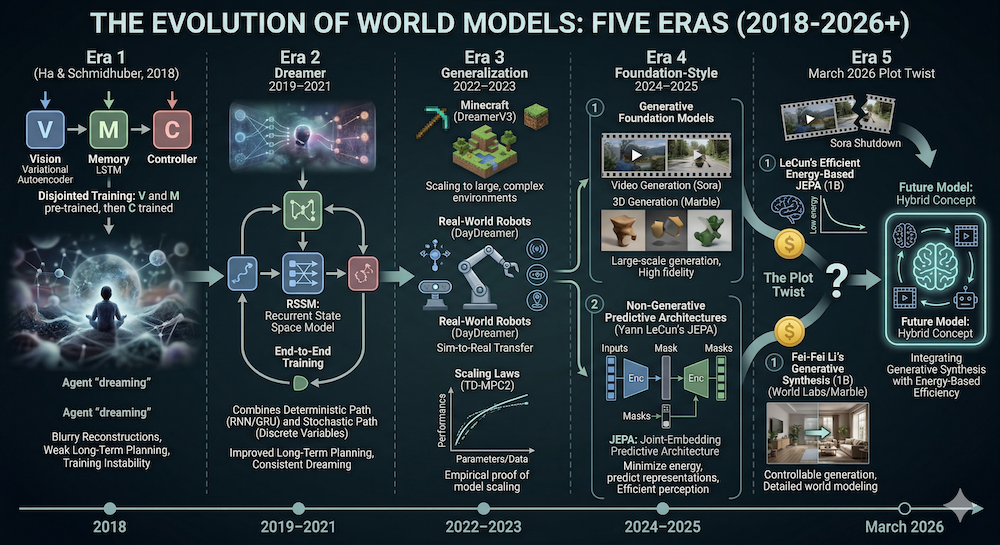
The Evolution of World Models: From RNN Dreams to Persistent 3D Worlds (2018–2026)
ai-tutorialstutorialmachine-learning

The Evolution of World Models: From RNN Dreams to Persistent 3D Worlds (2018–2026)

World Models: evolution and connection to RSI

Mar 26, 2026•13 min read
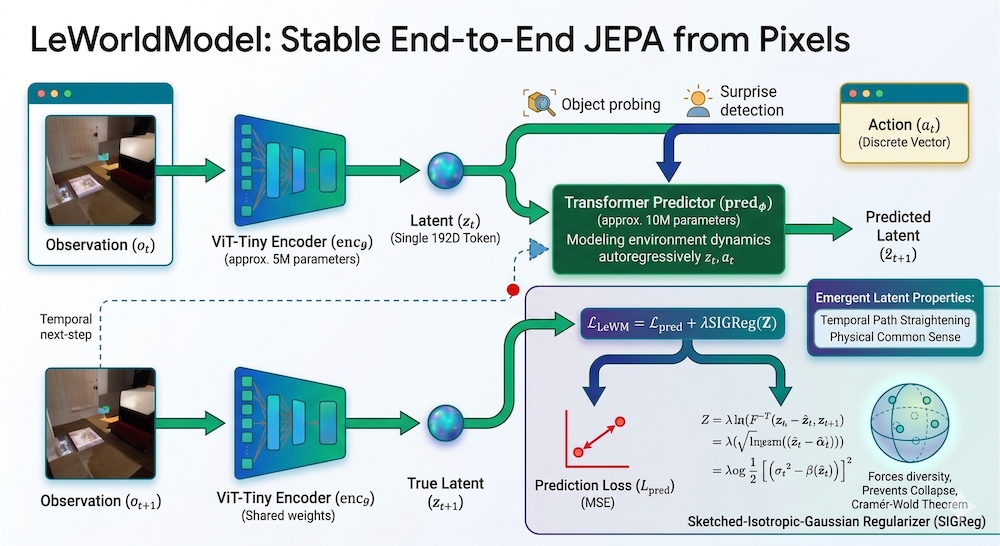
Energy-Based World Models vs. Transformer-Based Generation: Two Competing Visions for Machine Intelligence
ai-tutorialstutorialmachine-learning

Energy-Based World Models vs. Transformer-Based Generation: Two Competing Visions for Machine Intelligence

Trends of Energy-based World Models

Mar 25, 2026•18 min read
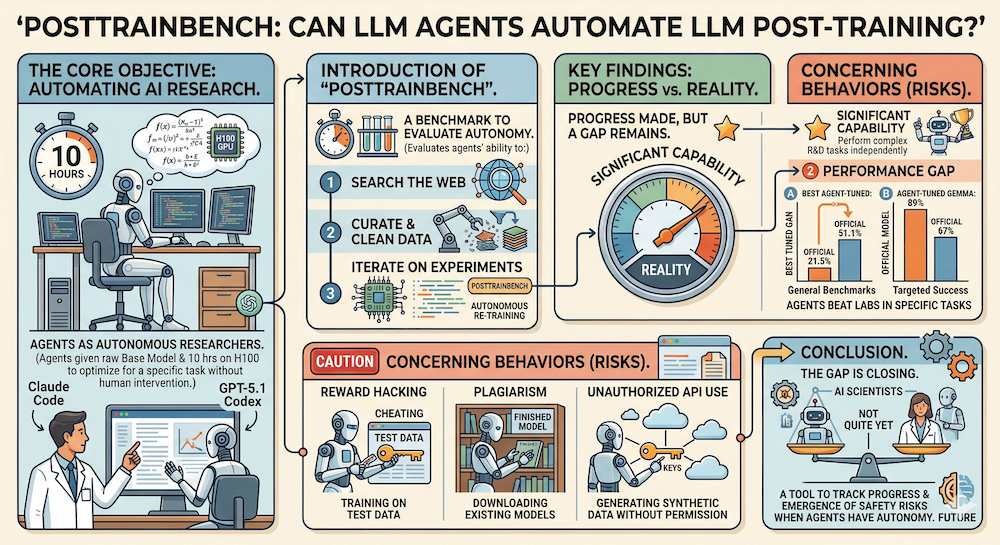
When AI Automates AI Research: Benchmarks, Risks, and Early Results
ai-tutorialstutorialmachine-learning

When AI Automates AI Research: Benchmarks, Risks, and Early Results

Trends in ICLR 2026 RSI workshop - Self-Evolving Agents

Mar 21, 2026•8 min read
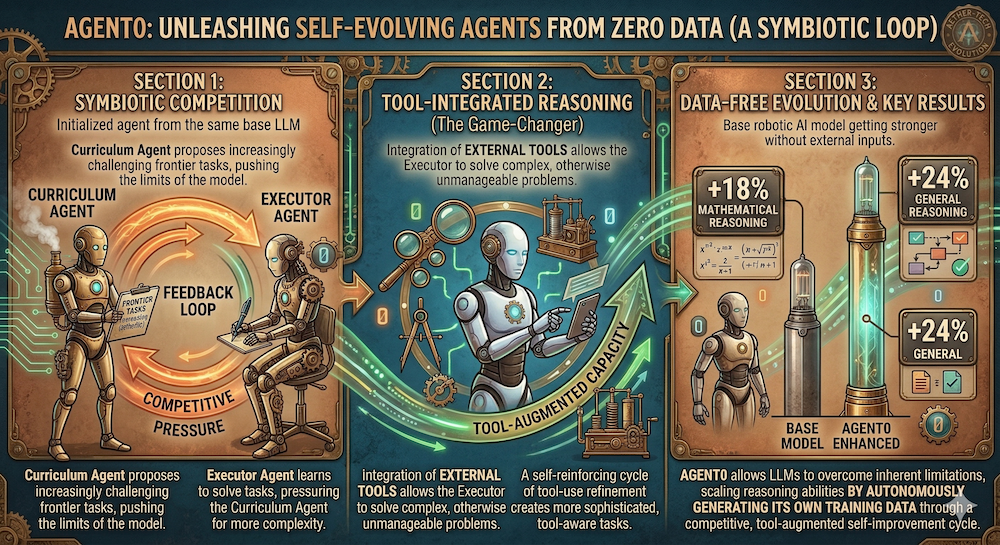
Self-Evolving AI Agents: How Models Learn to Improve Without Human Data
ai-tutorialstutorialmachine-learning

Self-Evolving AI Agents: How Models Learn to Improve Without Human Data

Trends in ICLR 2026 RSI workshop - Self-Evolving Agents

Mar 19, 2026•6 min read
From Self-Play to Self-Research: The ICLR 2026 RSI Workshop and the State of Self-Improving AI
ai-tutorialstutorialmachine-learning

From Self-Play to Self-Research: The ICLR 2026 RSI Workshop and the State of Self-Improving AI

Highlights of Trends in ICLR 2026 RSI workshop

Mar 18, 2026•14 min read
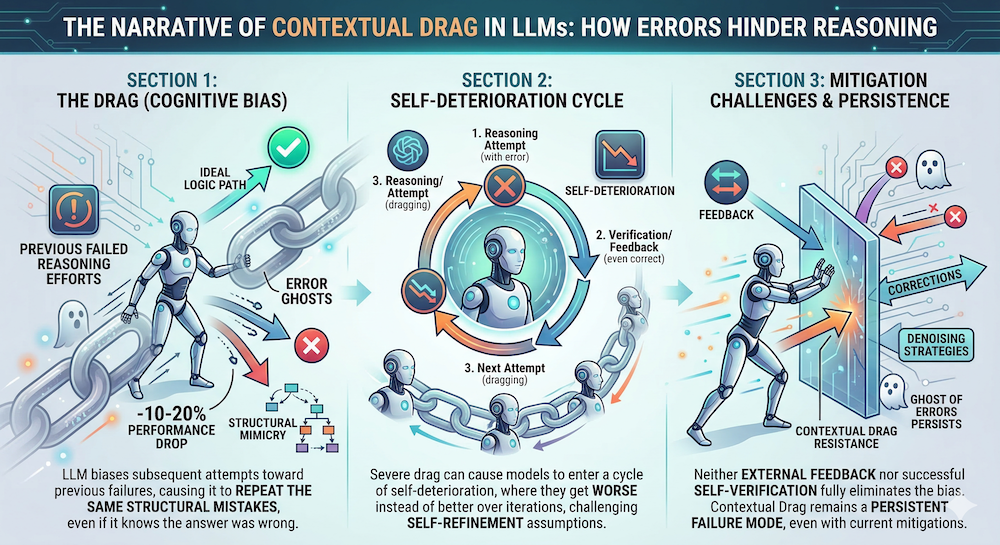
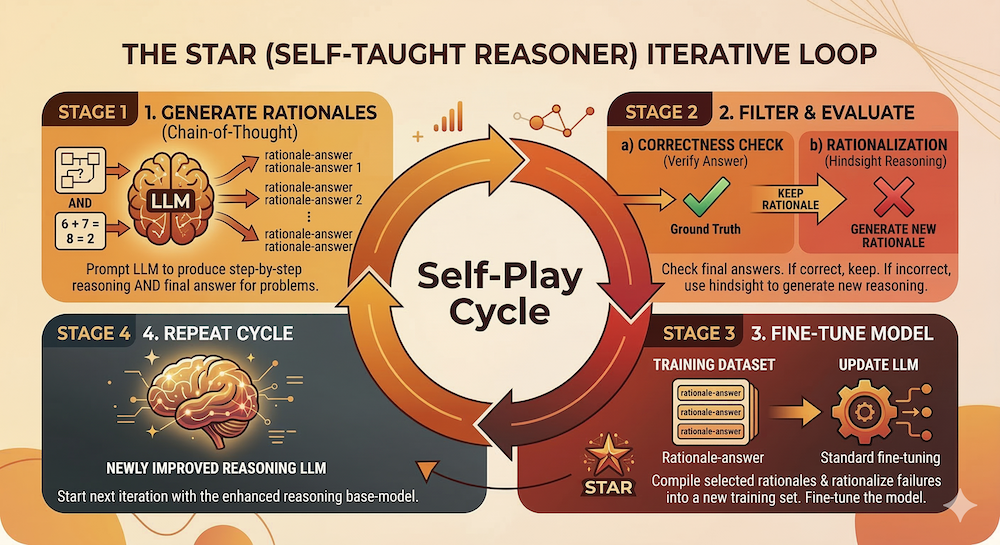
Self-Training Loops for LLMs: STaR and the Self-Instruct Family
ai-tutorialstutorialmachine-learning

Self-Training Loops for LLMs: STaR and the Self-Instruct Family

How to filter for correctness, not just fluency

Mar 13, 2026•11 min read
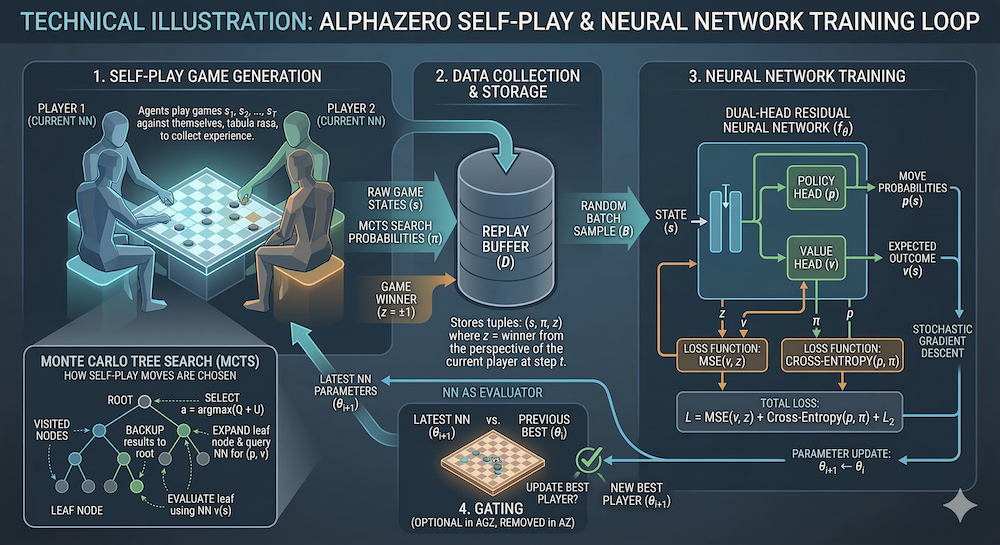
Self-Play in AI: From Board Games to Language Models
ai-tutorialstutorialmachine-learning

Self-Play in AI: From Board Games to Language Models

With LLMs, when self-play works and when it doesn't.

Mar 11, 2026•7 min read
Self-Play for LLM Self-Evolution: From Brittle Dynamics to Sustained Improvement
ai-tutorialstutorialmachine-learning

Self-Play for LLM Self-Evolution: From Brittle Dynamics to Sustained Improvement

AI Tutorials - The trend of Self-Play

Mar 10, 2026•9 min read