ai-tutorialstutorialoptimization
The Optimization Domain: Convexity, Rates, and Which of Your Training Claims Are Theorems
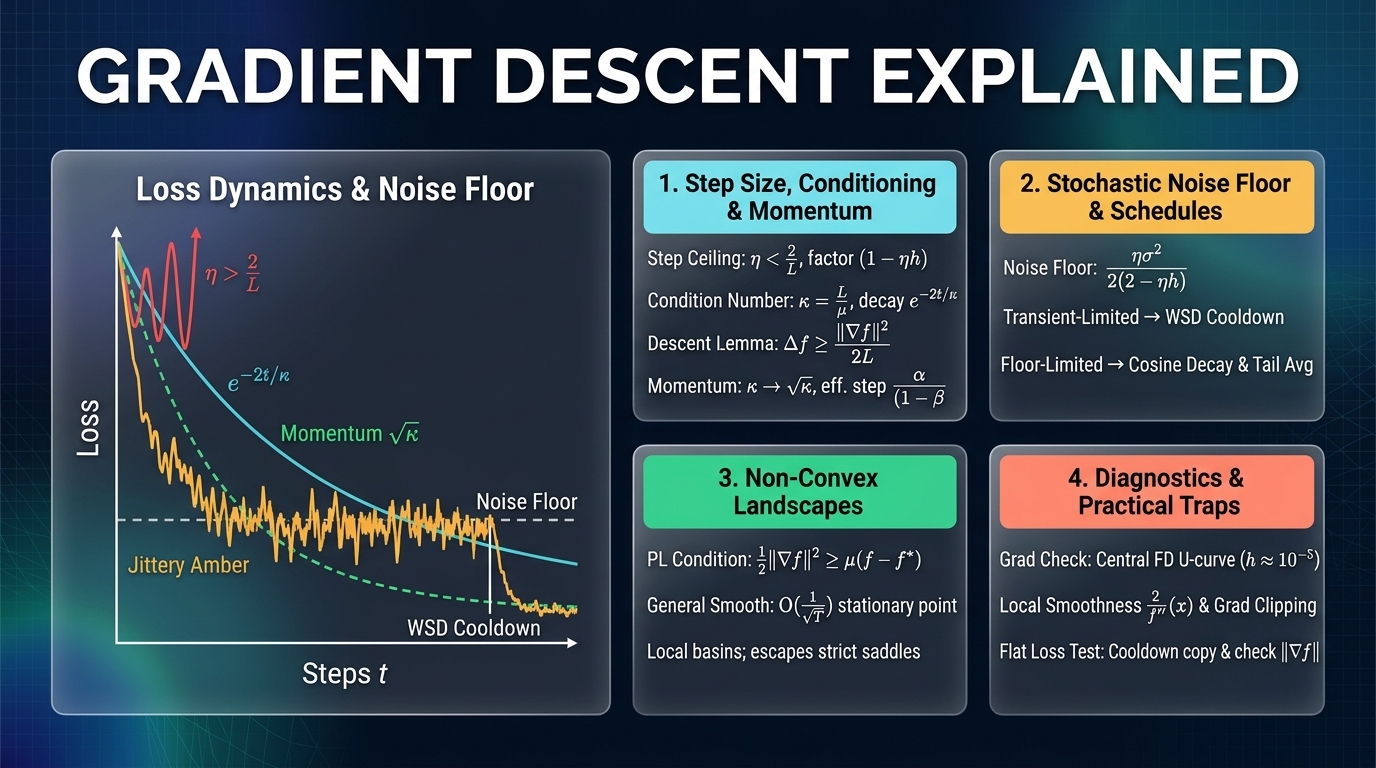
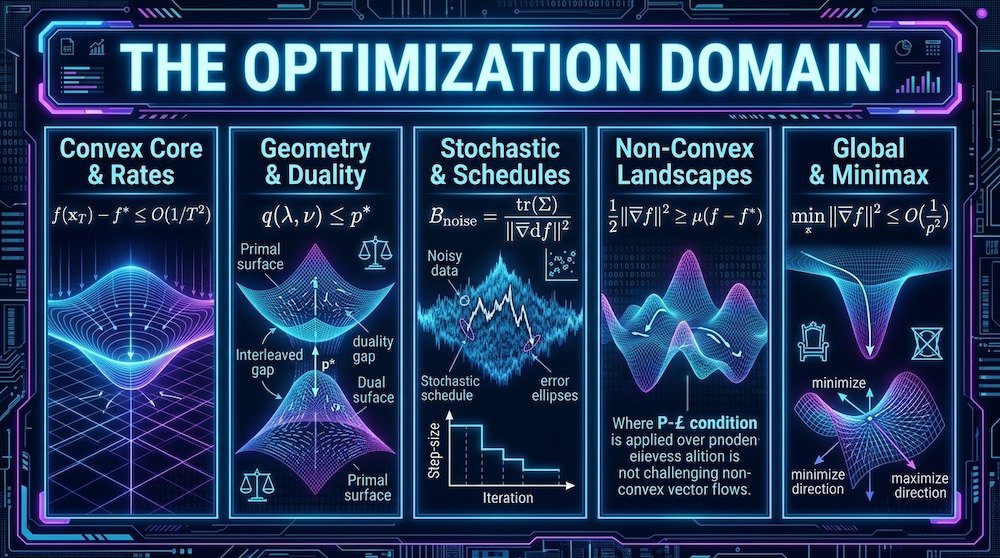
A standalone tutorial, not a survey: an optimization problem as a function and a set and a method as a sequence of oracle queries, what convexity buys and the one pathology it leaves, duality and KKT with the SVM's support vectors named by complementary slackness and the log-partition's conjugate as negative entropy, the rates of gradient descent, heavy ball and Nesterov against their theorems and against Nesterov's worst-case function, mirror descent and natural gradient as steepest descent under a different geometry, Adam as a diagonal preconditioner with the counter-example on which it fails and the block-heterogeneous quadratic on which it wins, Shampoo, SOAP and Muon as steepest descent under the spectral norm with the 2025–26 scoreboard quoted from the neutral benchmarks, the stochastic regime from the Robbins–Monro hand-off through the noise floor, the gradient noise scale, variance reduction, schedules on the noisy quadratic model, warmup and the equilibrium norm that weight decay actually sets, double descent with the bias–variance decomposition exact on the linear model and benign overfitting as the condition under which interpolating is harmless, what a stationary-point guarantee promises on a non-convex function and the lower bounds that say nothing more can be promised, saddles, Polyak–Łojasiewicz, the conservative-gradient theorem under autodiff on a ReLU net, benign landscapes, lazy versus feature learning, the edge of stability, implicit bias and the sharpness that is not a property of the function, deterministic global optimization from branch-and-bound through αBB and Lasserre to the ReLU verifiers where it is load-bearing today, Langevin, Bayesian optimization and quantization as the stochastic and discrete alternatives, minimax as not-descent, seventeen checkpoint exercises, a list of the common misreadings, and an appendix that grades every connection to our earlier posts by how much it actually proves.